FREE TOOLS · REAL TESTS ·98.7% FEWER TOKENS IN THIS TEST
SEVEN JOBS ADDED TOGETHER, NOT ANYONE'S LIVE WEEK
02 / THE SETUP
I'm sharing nine GitHub repos.
9 GITHUB REPOSAll free to use
STEP ONEInstall them once
on your own computer
GROK BOT TOKEN USAGE
CUT WAY DOWN
every job after sends less
Cut token usage as far as it goes.
03 / FROM THIS TO THIS
From this usage, to this usage.
Seven real jobs. Raw vs cleaned up. Added together. Not one week of use.
usage · before · raw dumps
BEFORE
4,343,098
tokens sent, 7 jobs
HIGH USAGE
The meter only goes up until reset.
Airport CSVraw dump
3,841,232
Costco Wikipedia pageraw dump
399,936
Two page copiesraw dump
35,425
Seven code filesraw dump
30,336
Nine GitHub API repliesraw dump
17,848
arXiv PDF textraw dump
12,792
jq last 30 commitsraw dump
5,529
usage · after the tools
AFTER
57,944
tokens sent, same 7 jobs
98.7% FEWER ABOUT 75x LESS
Same bar scale as the left board.
Clean articletrafilatura
26,938
Changes onlychangedetection.io
20,070
Clean PDF textDocling
7,900
Shrunk git logRTK
2,399
Matching linesripgrep
374
Filtered fieldsjq
174
SQL answer + queryDuckDB
89
IN THIS TEST. THESE 7 JOBS ADDED TOGETHER. TIKTOKEN CL100K_BASE ESTIMATE, NOT THE GROK BOT METER. NO DOLLAR OR CREDIT CLAIMS. TENACITY AND PYDANTIC NOT COUNTED.
04 / THE TEST
I ran seven jobs two ways.
First I sent the raw file. Then I sent the short version after a repo cleaned it up. Biggest first.
THIS TEST · MOST TO LEAST · RAW VS CLEANED UPMy test, not your Grok Bot bill
#WHAT I HADTHE REPOWHAT I SENT INSTEAD
1
Airport CSV3,841,232 tokens
DuckDB
SQL answer89 tokens
2
Costco Wikipedia page399,936 tokens
trafilatura
Clean article26,938 tokens
3
Two page copies35,425 tokens
changedetection.io
Changes only20,070 tokens
4
Seven code files30,336 tokens
ripgrep
Matching lines374 tokens
5
Nine GitHub API replies17,848 tokens
jq
Filtered fields174 tokens
6
arXiv PDF text12,792 tokens
Docling
Clean PDF text7,900 tokens
7
jq last 30 commits5,529 tokens
RTK
Shrunk git log2,399 tokens
Tenacity and Pydantic are not on this list. They do not shrink the text you send.
ILLUSTRATED FROM THIS TEST, TIKTOKEN CL100K_BASE ESTIMATE. NOT A REAL BILLING PAGE.
05 / THE NINE
The nine token cutters.
01trafilaturaKeeps only the article words
02jqPicks only the fields you need
03ripgrepFinds only the matching lines
04DuckDBAnswers a question about a CSV
05DoclingTurns a PDF into cleaner text
06changedetection.ioSends only what changed on a page
07RTKShrinks long command output
08TenacityRetries one failed call
09PydanticChecks the answer has the right shape
06 / HOW WE PROVE IT
How we prove it.
1
STEP 1Pick a real job
a real page, file or API
2
STEP 2Do it the long way
save what the bot would read
3
STEP 3Do it with the tool
same job, same source
4
STEP 4Count both
characters and tokens
REAL SOURCES
Wikipedia, the GitHub API, a public CSV, an arXiv PDF
HOW WE COUNT
tiktoken cl100k_base, on the exact text
THE FINE PRINT
Numbers from this test only. Not the Grok Bot meter.
07 / REPO 1 OF 9
01
REPO 1 OF 9 · TRAFILATURA
Strip the page, keep the words.
This tool reads a messy webpage and keeps only the article words. It drops menus, ads, and page code.
github.com/adbar/trafilatura
93.3%FEWER TOKENS IN THIS TEST
08 / TRAFILATURA · THE STEPS
010203040506070809
How to use trafilatura.
1STEP 1Save the webpage.
2STEP 2Run trafilatura on your computer.
3STEP 3Send the clean article to Grok Bot, not the whole page.
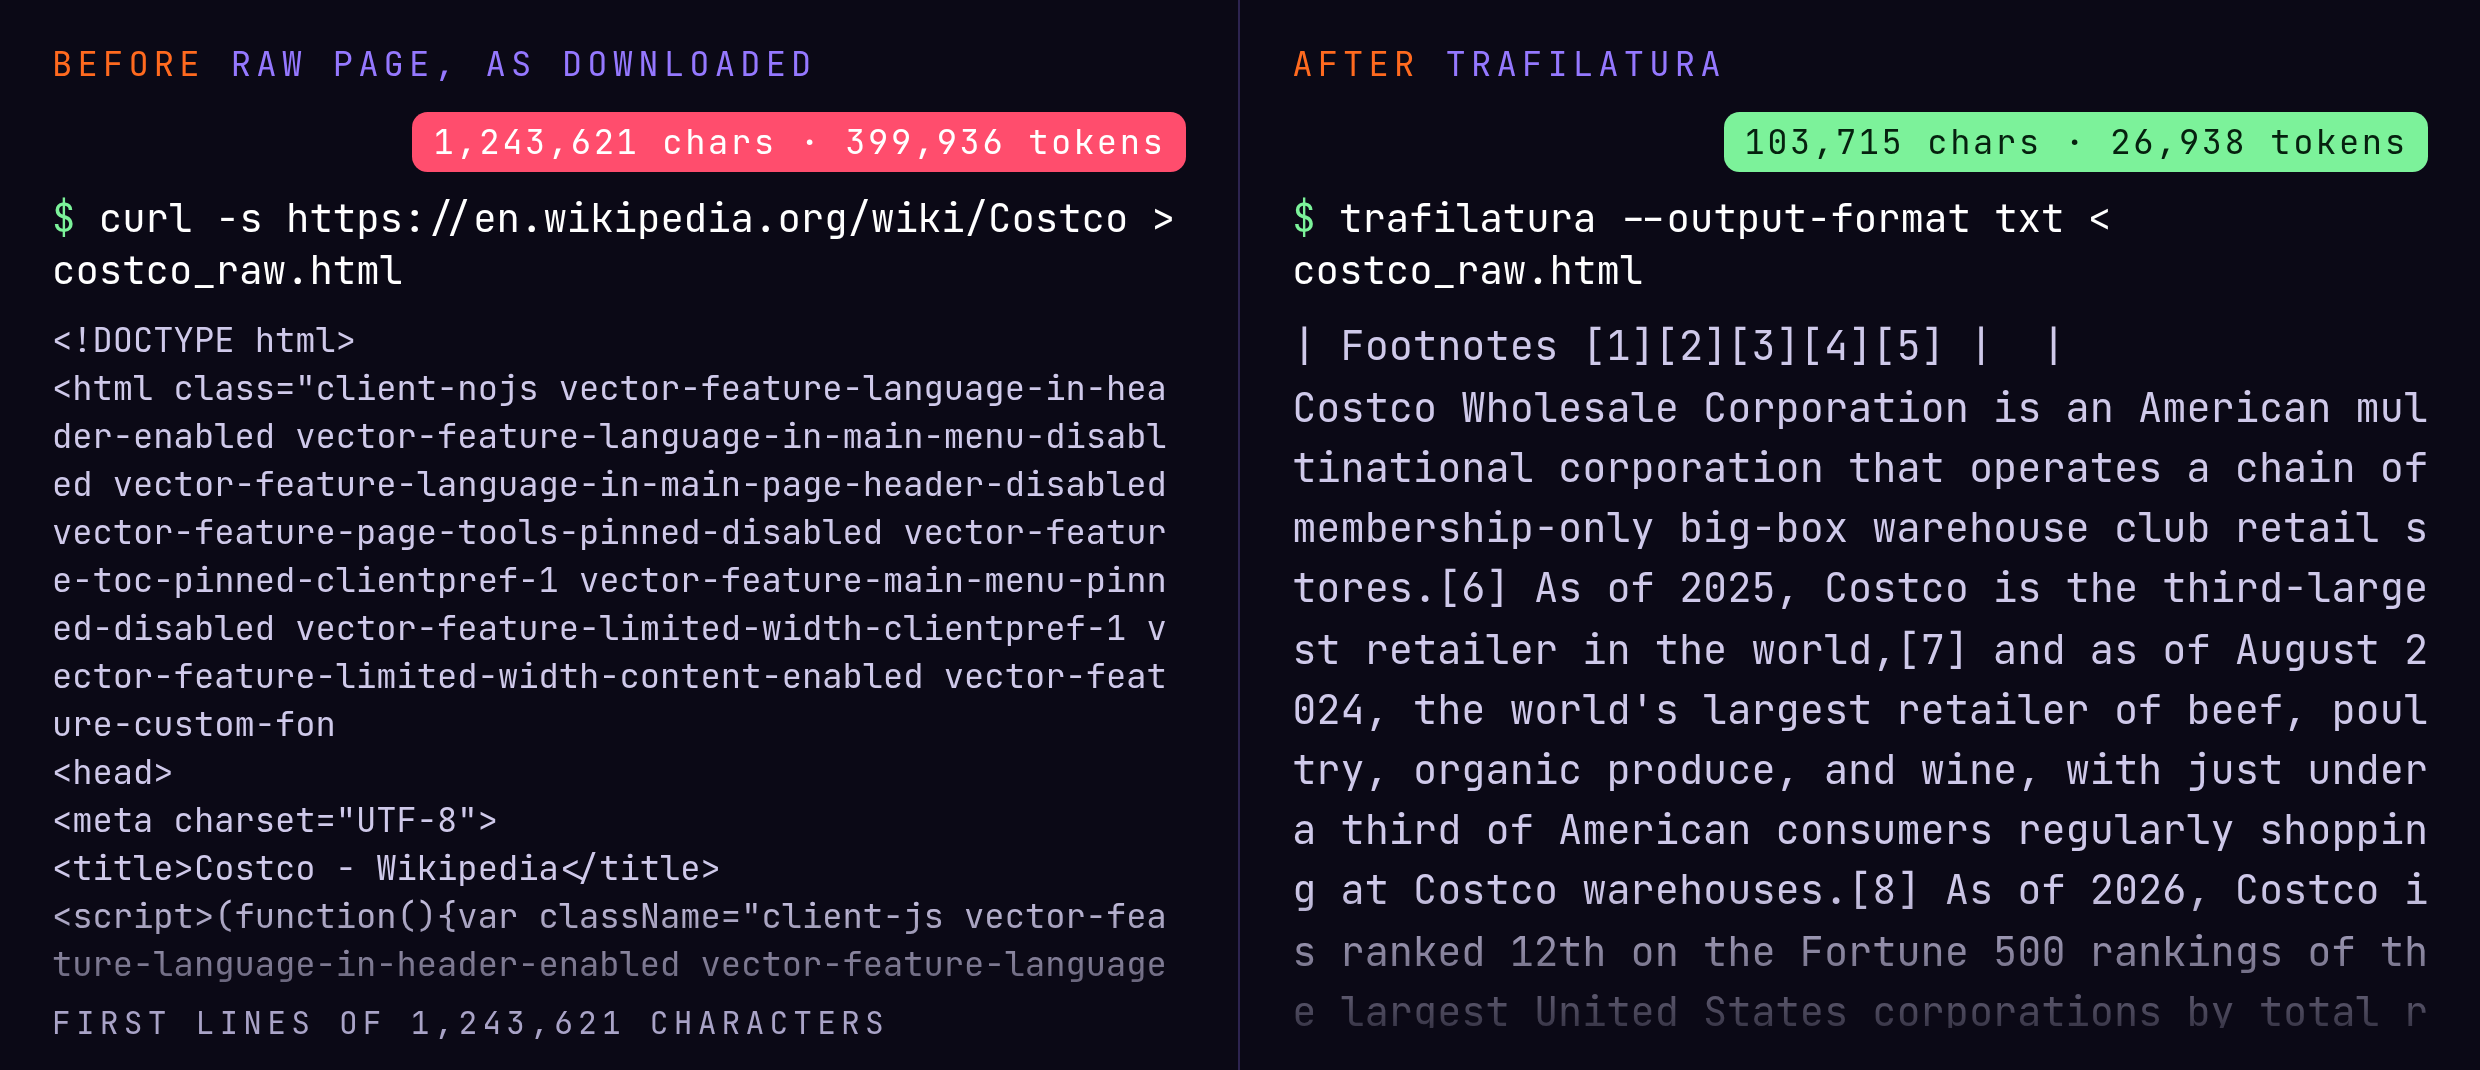
WHAT I TYPEDtrafilatura --output-format txt < costco_raw.html
09 / TRAFILATURA · THE EXAMPLE
010203040506070809
MY TEST · TRAFILATURA
I downloaded the Costco page from Wikipedia. It was a messy page full of menus and code, 399,936 tokens. I ran trafilatura on my computer. It kept only the article words. That clean article was 26,938 tokens.
my files · left: the raw Costco page · right: the clean article
10 / TRAFILATURA · THE RESULT
010203040506070809
93.3% fewer tokens. Same article.
BEFORE · THE RAW PAGE399,936tokens · 1,243,621 characters
AFTER · THE CLEAN ARTICLE26,938tokens · 103,715 characters
93.3%FEWER TOKENS ABOUT 14.8x LESS
WHAT THIS MEANSI sent the article, not the junk around it.
IN THIS TEST. TIKTOKEN CL100K_BASE ESTIMATE, NOT THE GROK BOT METER. SOURCE: en.wikipedia.org/wiki/Costco
11 / REPO 2 OF 9
02
REPO 2 OF 9 · JQ
Pick the fields you asked for.
This tool looks at a big reply from a website and keeps only the bits you asked for, like the name and the star count.
github.com/jqlang/jq
99.0%FEWER TOKENS IN THIS TEST
12 / JQ · THE STEPS
010203040506070809
How to use jq.
1STEP 1Get the big reply.
2STEP 2Tell jq which bits you want.
3STEP 3Send only those bits to Grok Bot.
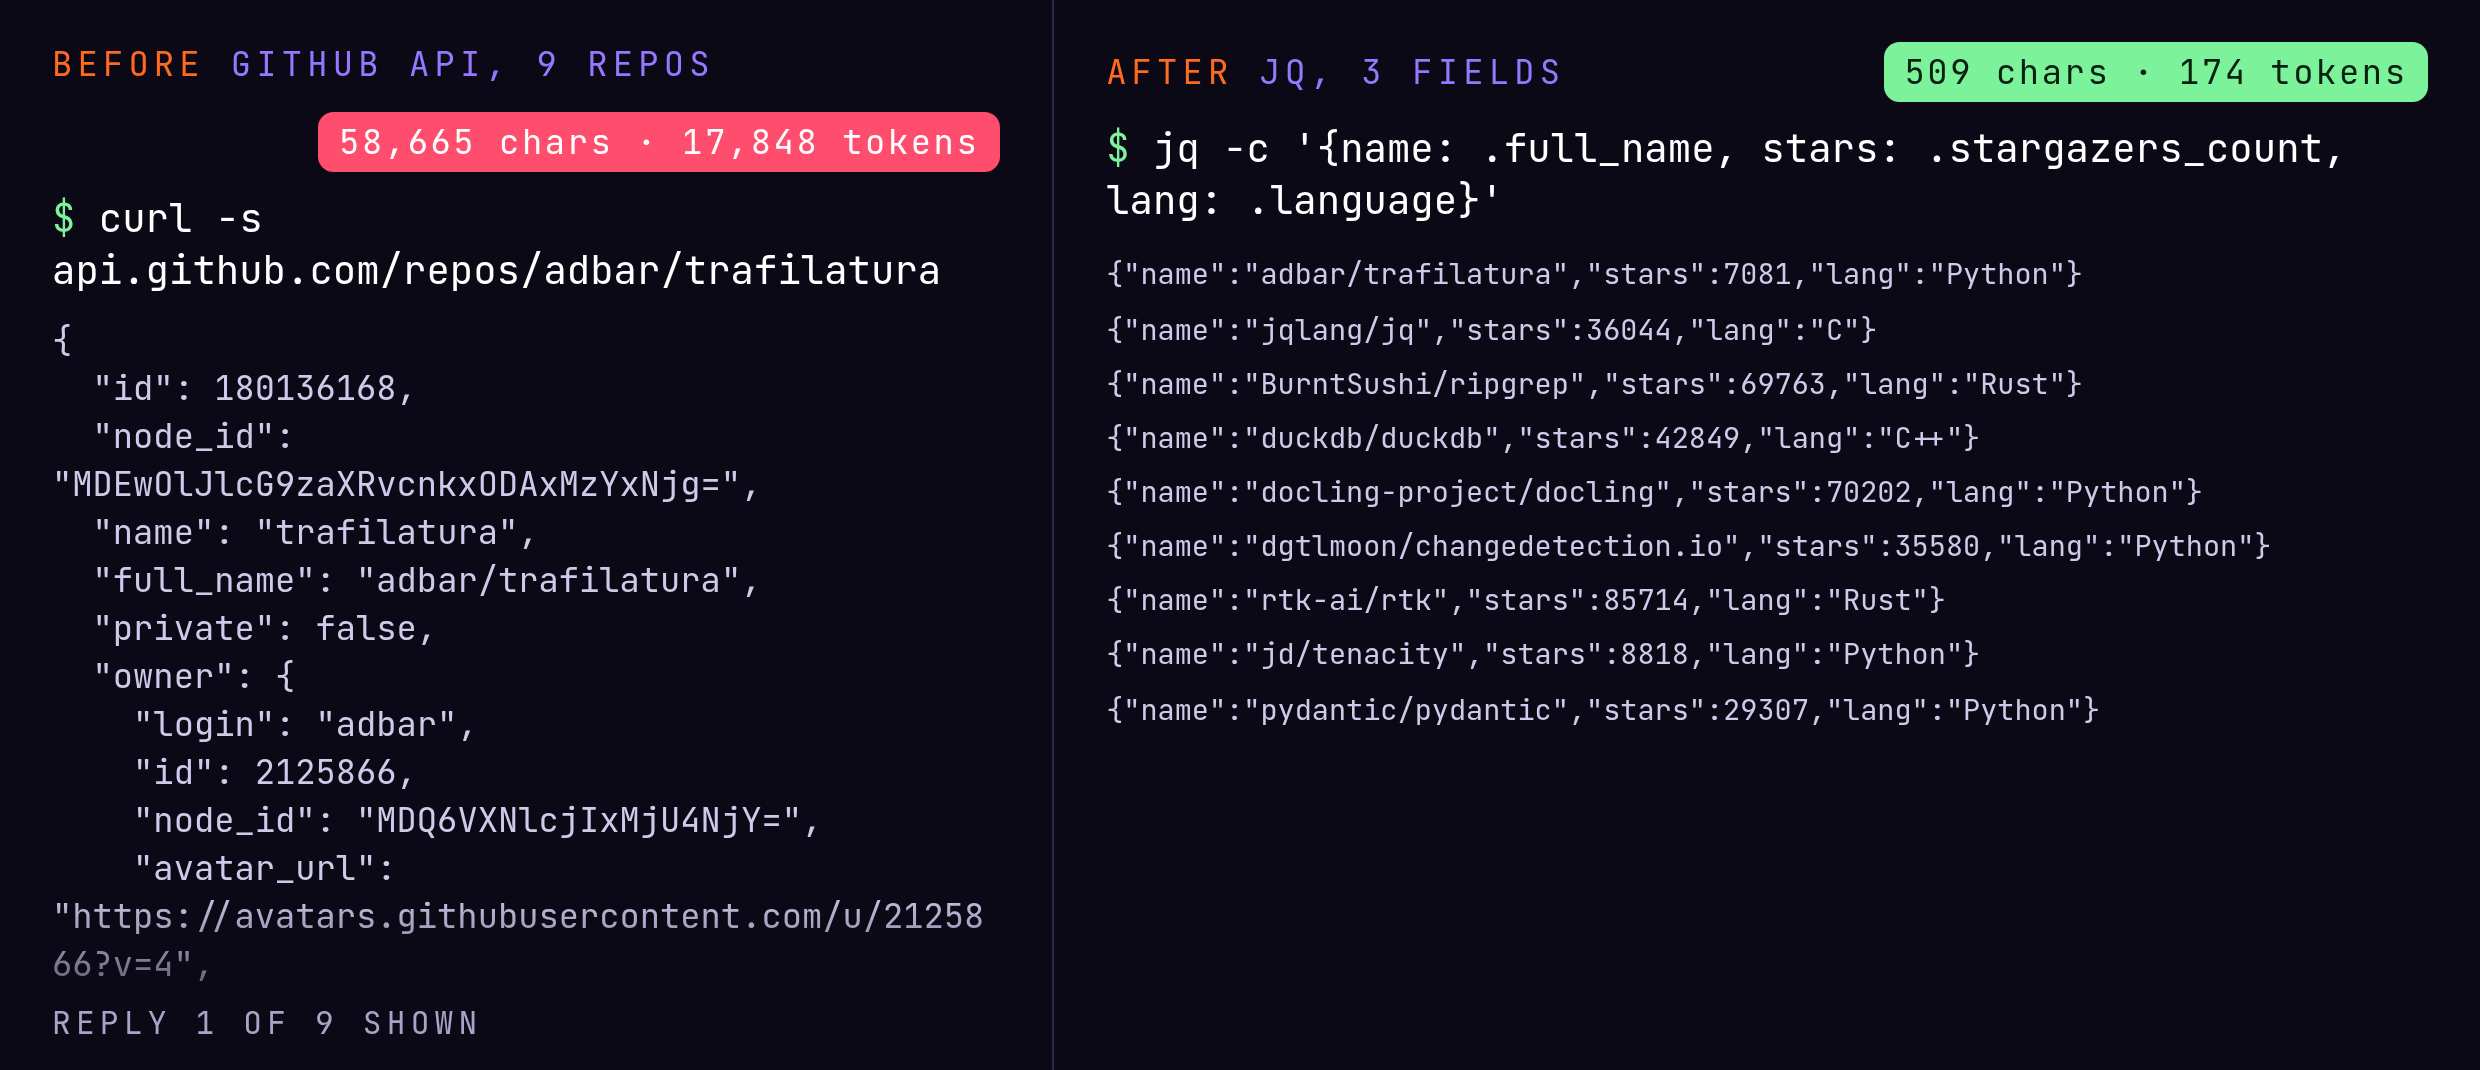
WHAT I TYPEDjq -c '{name: .full_name, stars: .stargazers_count, lang: .language}'
13 / JQ · THE EXAMPLE
010203040506070809
MY TEST · JQ
I asked GitHub about 9 repos. The full replies were packed with extra details I did not need, 17,848 tokens. I asked jq for only 3 things: the name, the star count, and the language. That short list was 174 tokens.
my files · left: one full GitHub reply · right: the 3 things for all 9 repos
14 / JQ · THE RESULT
010203040506070809
99.0% fewer tokens. Same 3 things.
BEFORE · 9 FULL REPLIES17,848tokens · 58,665 characters
AFTER · 3 THINGS EACH174tokens · 509 characters
99.0%FEWER TOKENS ABOUT 102.6x LESS
WHAT THIS MEANSI sent 3 things, not the whole reply.
IN THIS TEST. TIKTOKEN CL100K_BASE ESTIMATE, NOT THE GROK BOT METER. SOURCE: api.github.com, 9 repos
15 / REPO 3 OF 9
03
REPO 3 OF 9 · RIPGREP
Find the lines, skip the rest.
This tool searches your files and gives you only the lines that match.
github.com/BurntSushi/ripgrep
98.8%FEWER TOKENS IN THIS TEST
16 / RIPGREP · THE STEPS
010203040506070809
How to use ripgrep.
1STEP 1Keep the files on your computer.
2STEP 2Search for the word you need.
3STEP 3Send only the matching lines to Grok Bot.
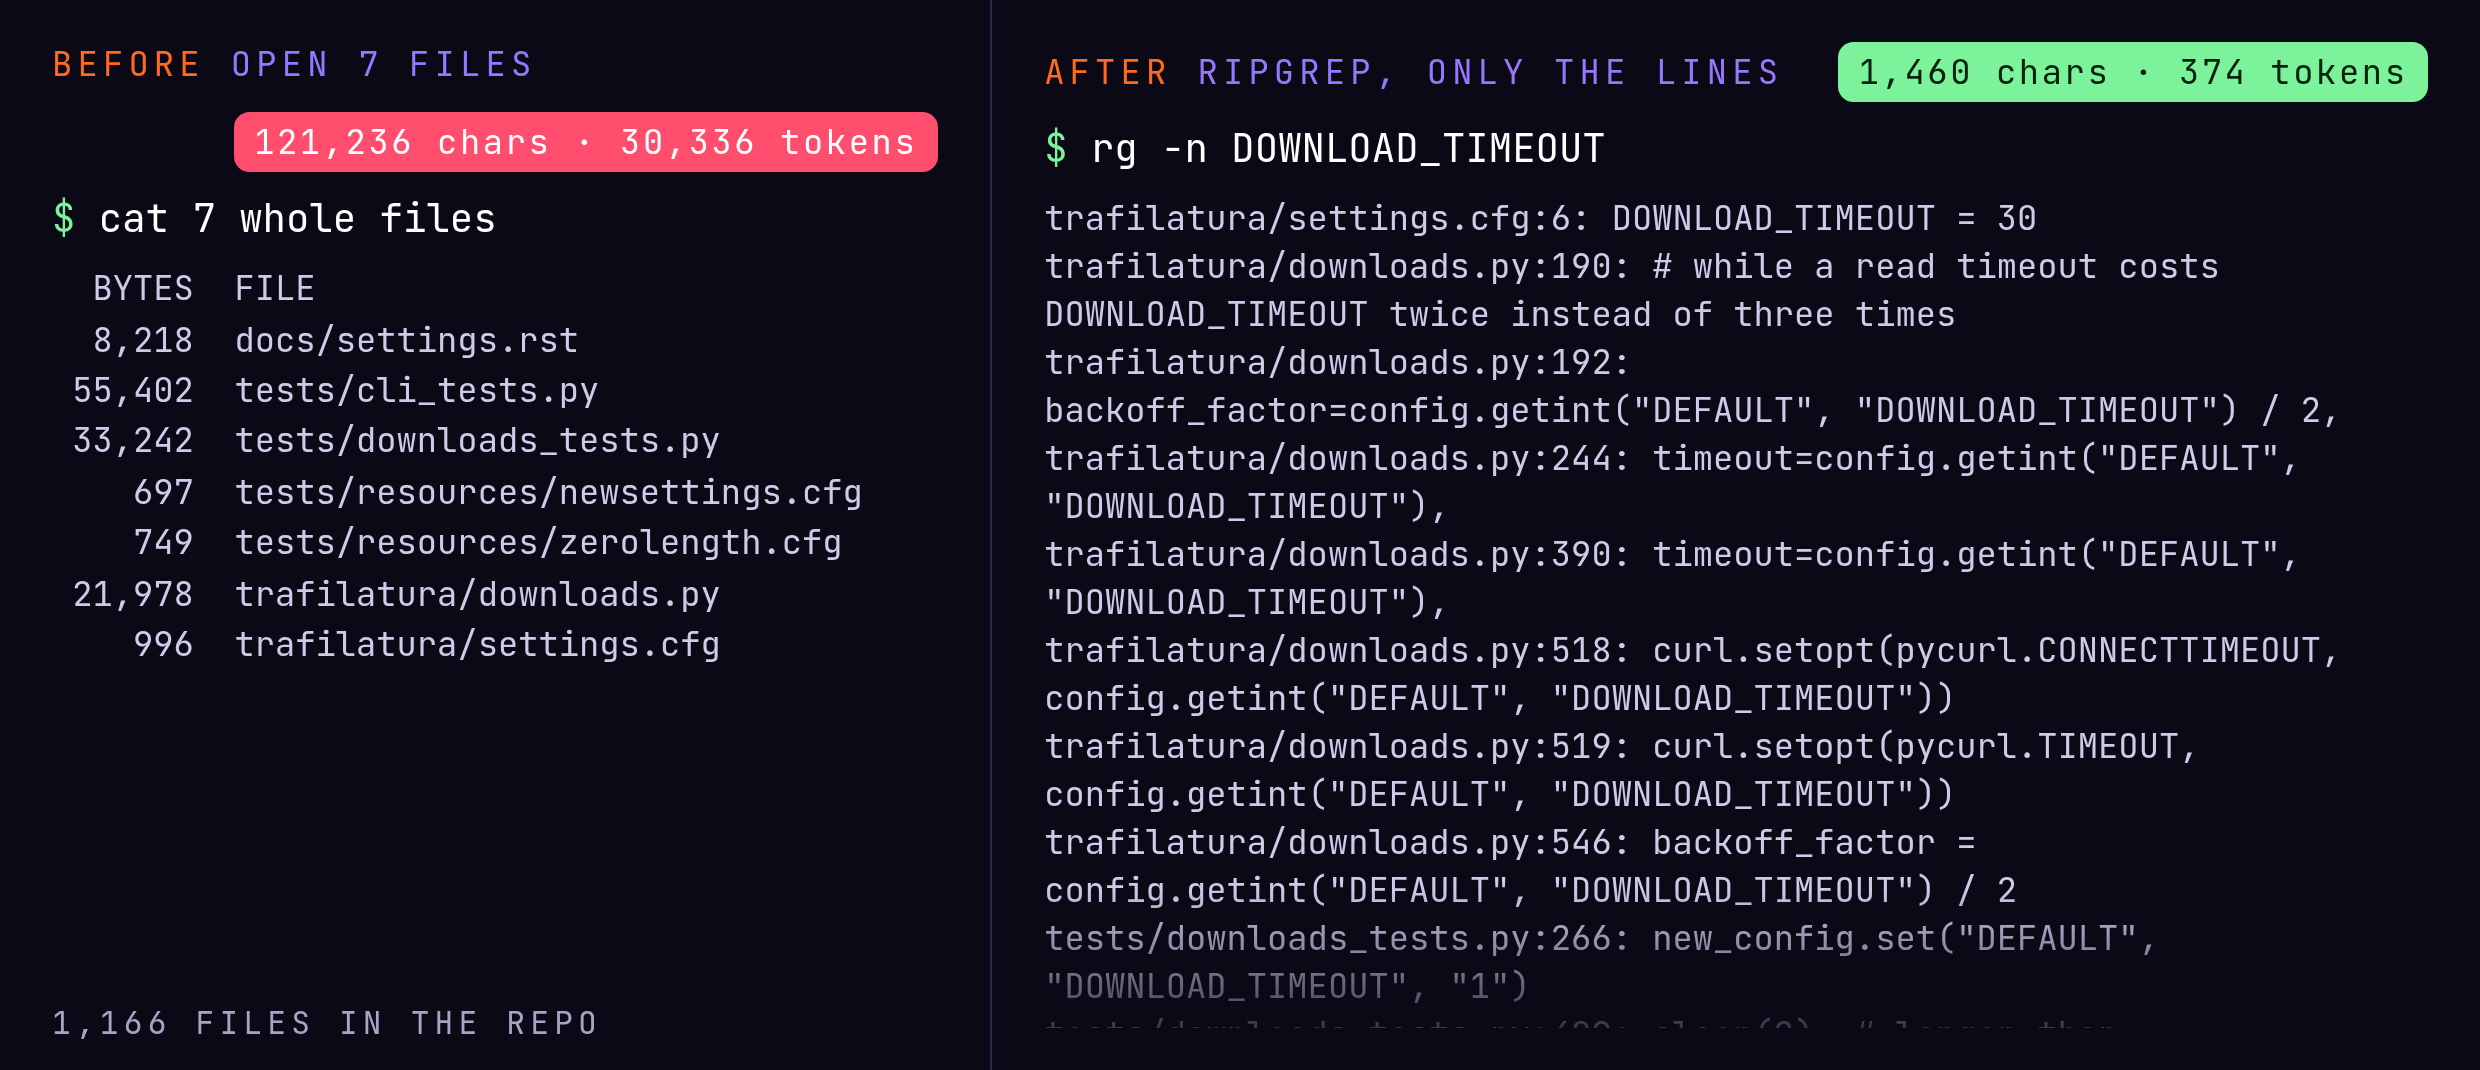
WHAT I TYPEDrg -n DOWNLOAD_TIMEOUT
17 / RIPGREP · THE EXAMPLE
010203040506070809
MY TEST · RIPGREP
I had 7 whole code files that contained the words DOWNLOAD_TIMEOUT, 30,336 tokens. Instead of pasting all 7 files, I searched them on my computer with ripgrep. It found 16 matching lines. Those 16 lines were 374 tokens.
my files · left: the 7 whole files · right: the 16 matching lines
18 / RIPGREP · THE RESULT
010203040506070809
98.8% fewer tokens. Same answer.
BEFORE · 7 WHOLE FILES30,336tokens · 121,236 characters
AFTER · 16 MATCHING LINES374tokens · 1,460 characters
98.8%FEWER TOKENS ABOUT 81.1x LESS
WHAT THIS MEANSI sent 16 lines, not 7 whole files.
IN THIS TEST. TIKTOKEN CL100K_BASE ESTIMATE, NOT THE GROK BOT METER. SOURCE: adbar/trafilatura code, 7 files
19 / REPO 4 OF 9
04
REPO 4 OF 9 · DUCKDB
Ask the spreadsheet, don't paste it.
This tool answers a question about a big spreadsheet so you do not have to paste the whole file.
github.com/duckdb/duckdb
99.99%FEWER TOKENS IN THIS TEST
20 / DUCKDB · THE STEPS
010203040506070809
How to use DuckDB.
1STEP 1Keep the spreadsheet on your computer.
2STEP 2Ask DuckDB one question.
3STEP 3Send the question and the short answer to Grok Bot, not the spreadsheet.
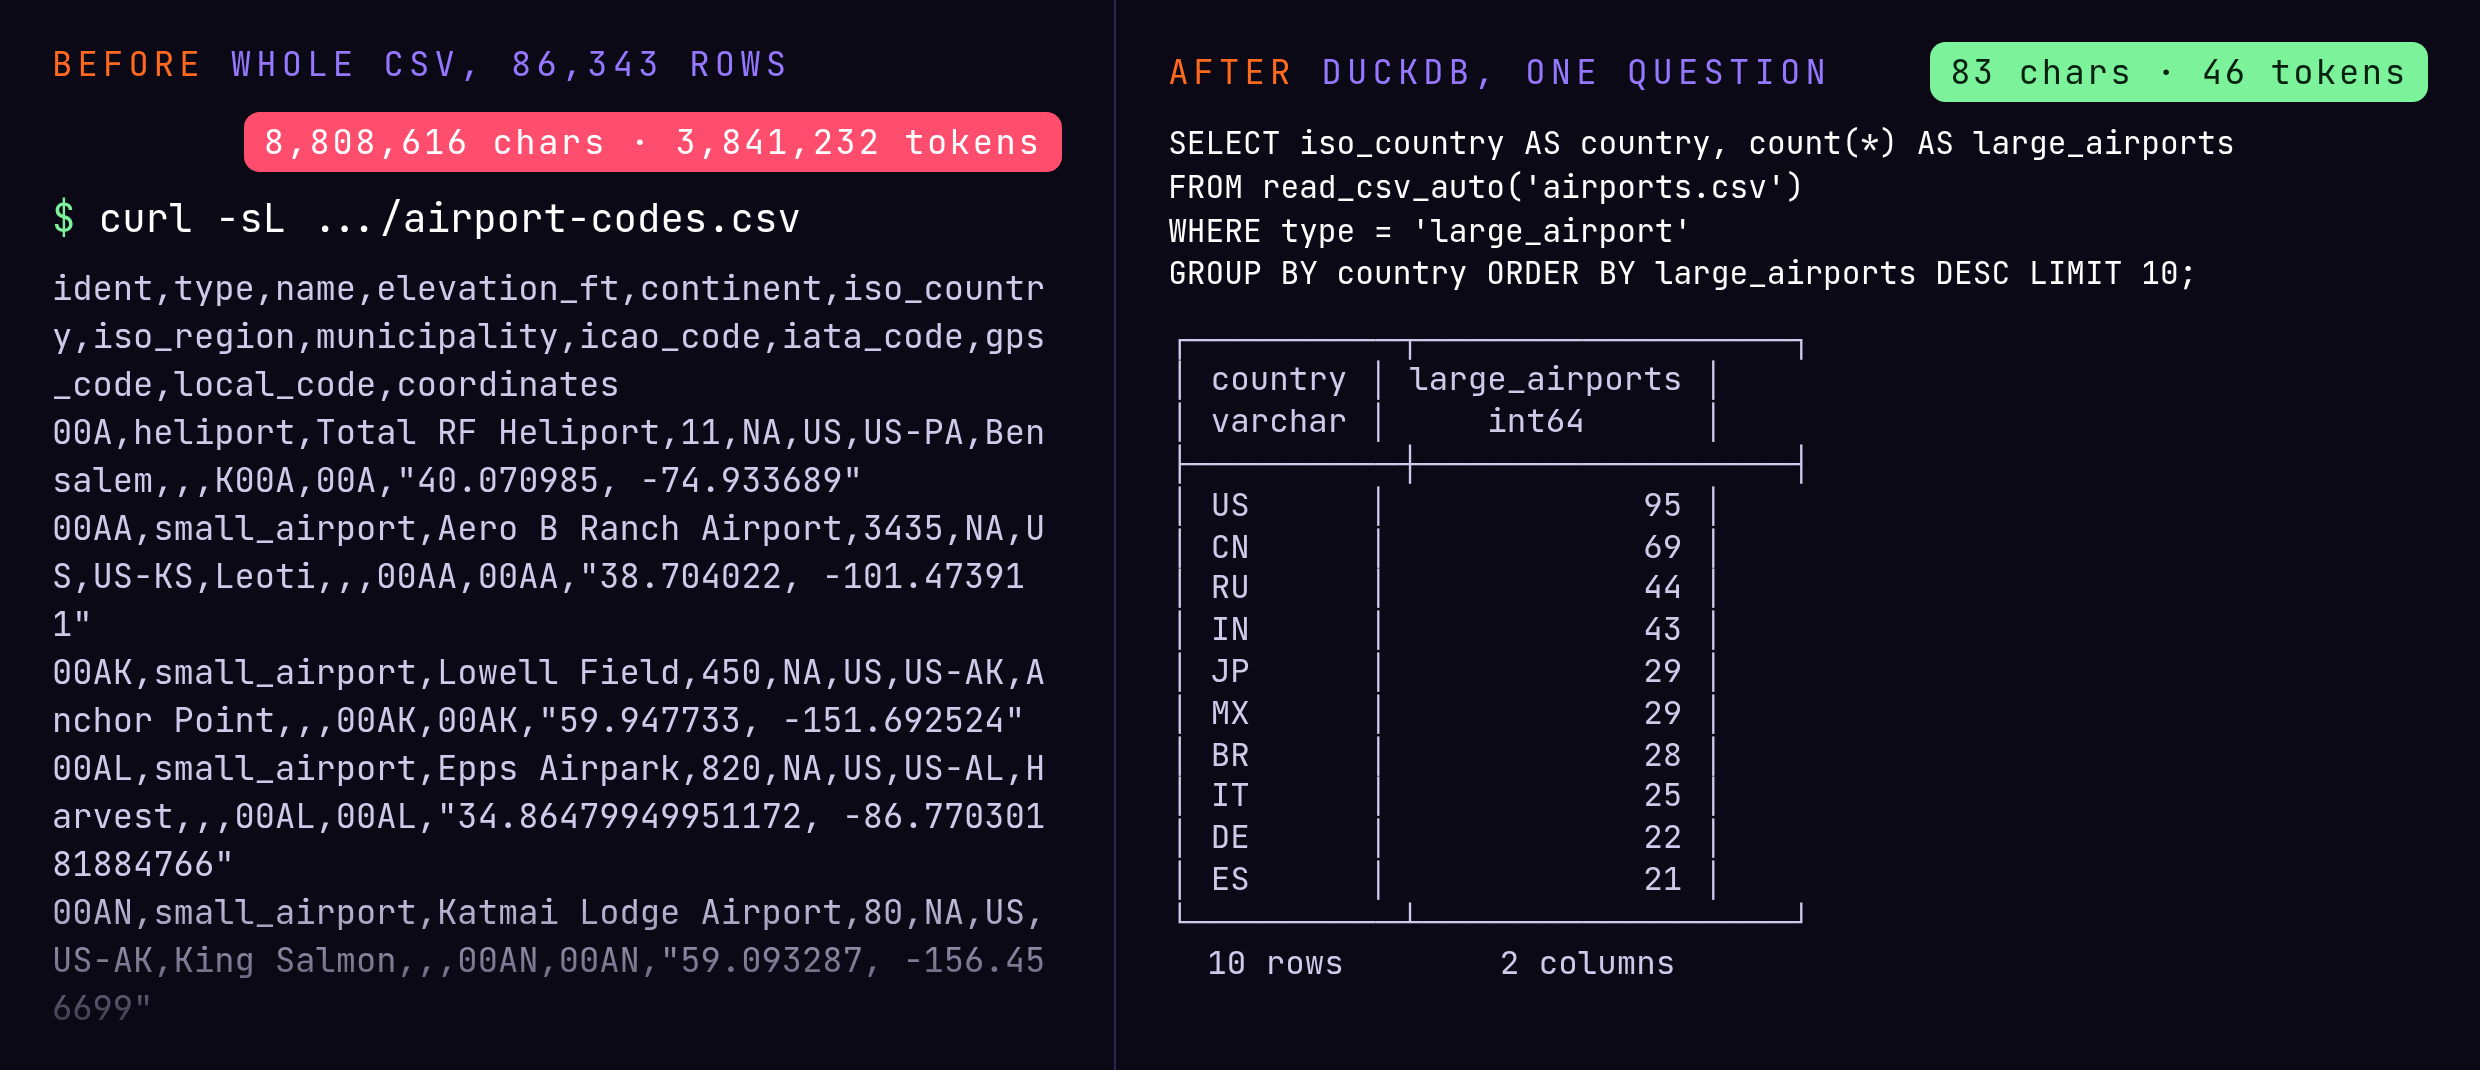
WHAT I TYPEDduckdb.sql(open("query.sql").read())
21 / DUCKDB · THE EXAMPLE
010203040506070809
MY TEST · DUCKDB
I had a list of 86,343 airports. Pasting that whole file would have been 3,841,232 tokens. I did not paste it. I asked DuckDB on my computer which countries have the most large airports. It gave me 10 countries, like the US with 95 and China with 69. I would send only that question and that short list, 89 tokens.
my files · left: the airport list · right: my question and the 10-row answer
The green tag on the right says 46 tokens. That is the 10-row answer alone. Add my 43-token question and I send 89 tokens.
22 / DUCKDB · THE RESULT
010203040506070809
99.99% fewer tokens. Same top 10.
BEFORE · THE WHOLE AIRPORT LIST3,841,232tokens · 8,808,616 characters
WHAT THIS MEANSI sent one question and a short answer, not the whole spreadsheet.
IN THIS TEST. TIKTOKEN CL100K_BASE ESTIMATE, NOT THE GROK BOT METER. SOURCE: datasets/airport-codes, 86,343 rows
23 / REPO 5 OF 9
05
REPO 5 OF 9 · DOCLING
Turn a PDF into cleaner text.
This tool turns a PDF into cleaner text that is easier to send and read.
github.com/docling-project/docling
38.2%FEWER TOKENS IN THIS TEST
24 / DOCLING · THE STEPS
010203040506070809
How to use Docling.
1STEP 1Save the PDF.
2STEP 2Run Docling on your computer.
3STEP 3Send the cleaner text to Grok Bot, not a messy PDF dump.
WHAT I TYPEDdocling convert docling_report.pdf --to md
25 / DOCLING · THE EXAMPLE
010203040506070809
MY TEST · DOCLING
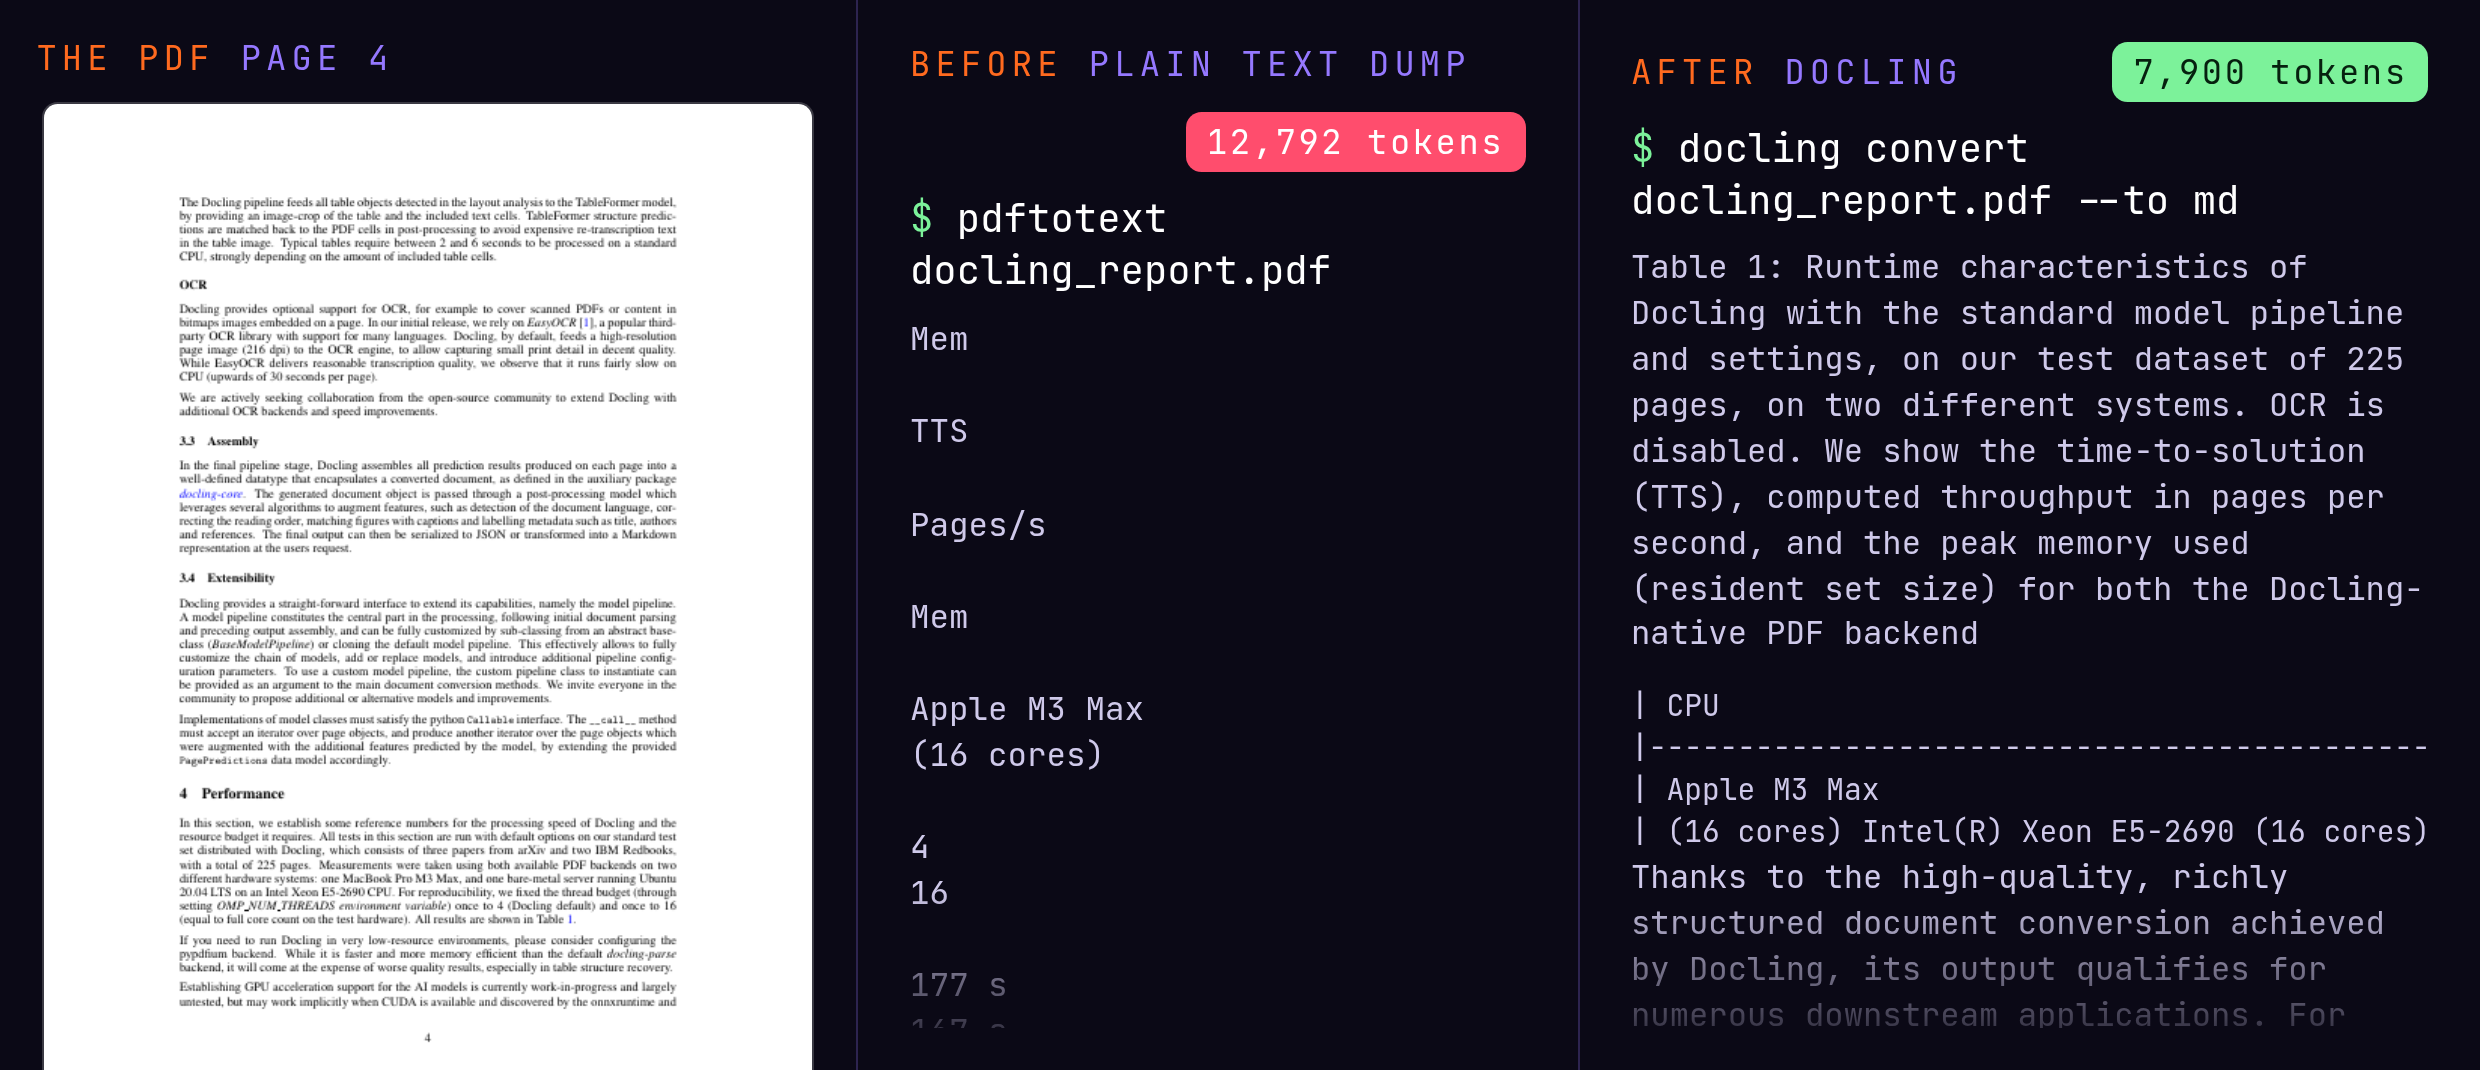
I used a 9-page PDF, the Docling technical report from arXiv. A plain dump of the PDF text was 12,792 tokens. I ran Docling. It turned the PDF into cleaner text with headings and tables, 7,900 tokens.
my files · left: plain PDF text dump · right: Docling cleaner text
26 / DOCLING · THE RESULT
010203040506070809
38.2% fewer tokens. Tables kept.
BEFORE · PLAIN PDF DUMP12,792tokens · 48,439 characters
AFTER · DOCLING TEXT7,900tokens · 34,063 characters
38.2%FEWER TOKENS ABOUT 1.6x LESS
WHAT THIS MEANSSame paper, cleaner and shorter. Text inside pictures is left out.
IN THIS TEST. TIKTOKEN CL100K_BASE ESTIMATE, NOT THE GROK BOT METER. SOURCE: arXiv 2408.09869, docling_report.pdf, 9 pages
27 / REPO 6 OF 9
06
REPO 6 OF 9 · CHANGEDETECTION.IO
Send only what changed.
This tool watches a webpage and sends you only what changed.
github.com/dgtlmoon/changedetection.io
43.3%FEWER TOKENS IN THIS TEST
28 / CHANGEDETECTION.IO · THE STEPS
010203040506070809
How to use changedetection.io.
1STEP 1Point it at a page.
2STEP 2When the page changes, it writes down the difference.
3STEP 3Send only that difference to Grok Bot, not the whole page again.
WHAT I DIDAdd the page to my watch list, then read the change
29 / CHANGEDETECTION.IO · THE EXAMPLE
010203040506070809
MY TEST · CHANGEDETECTION.IO
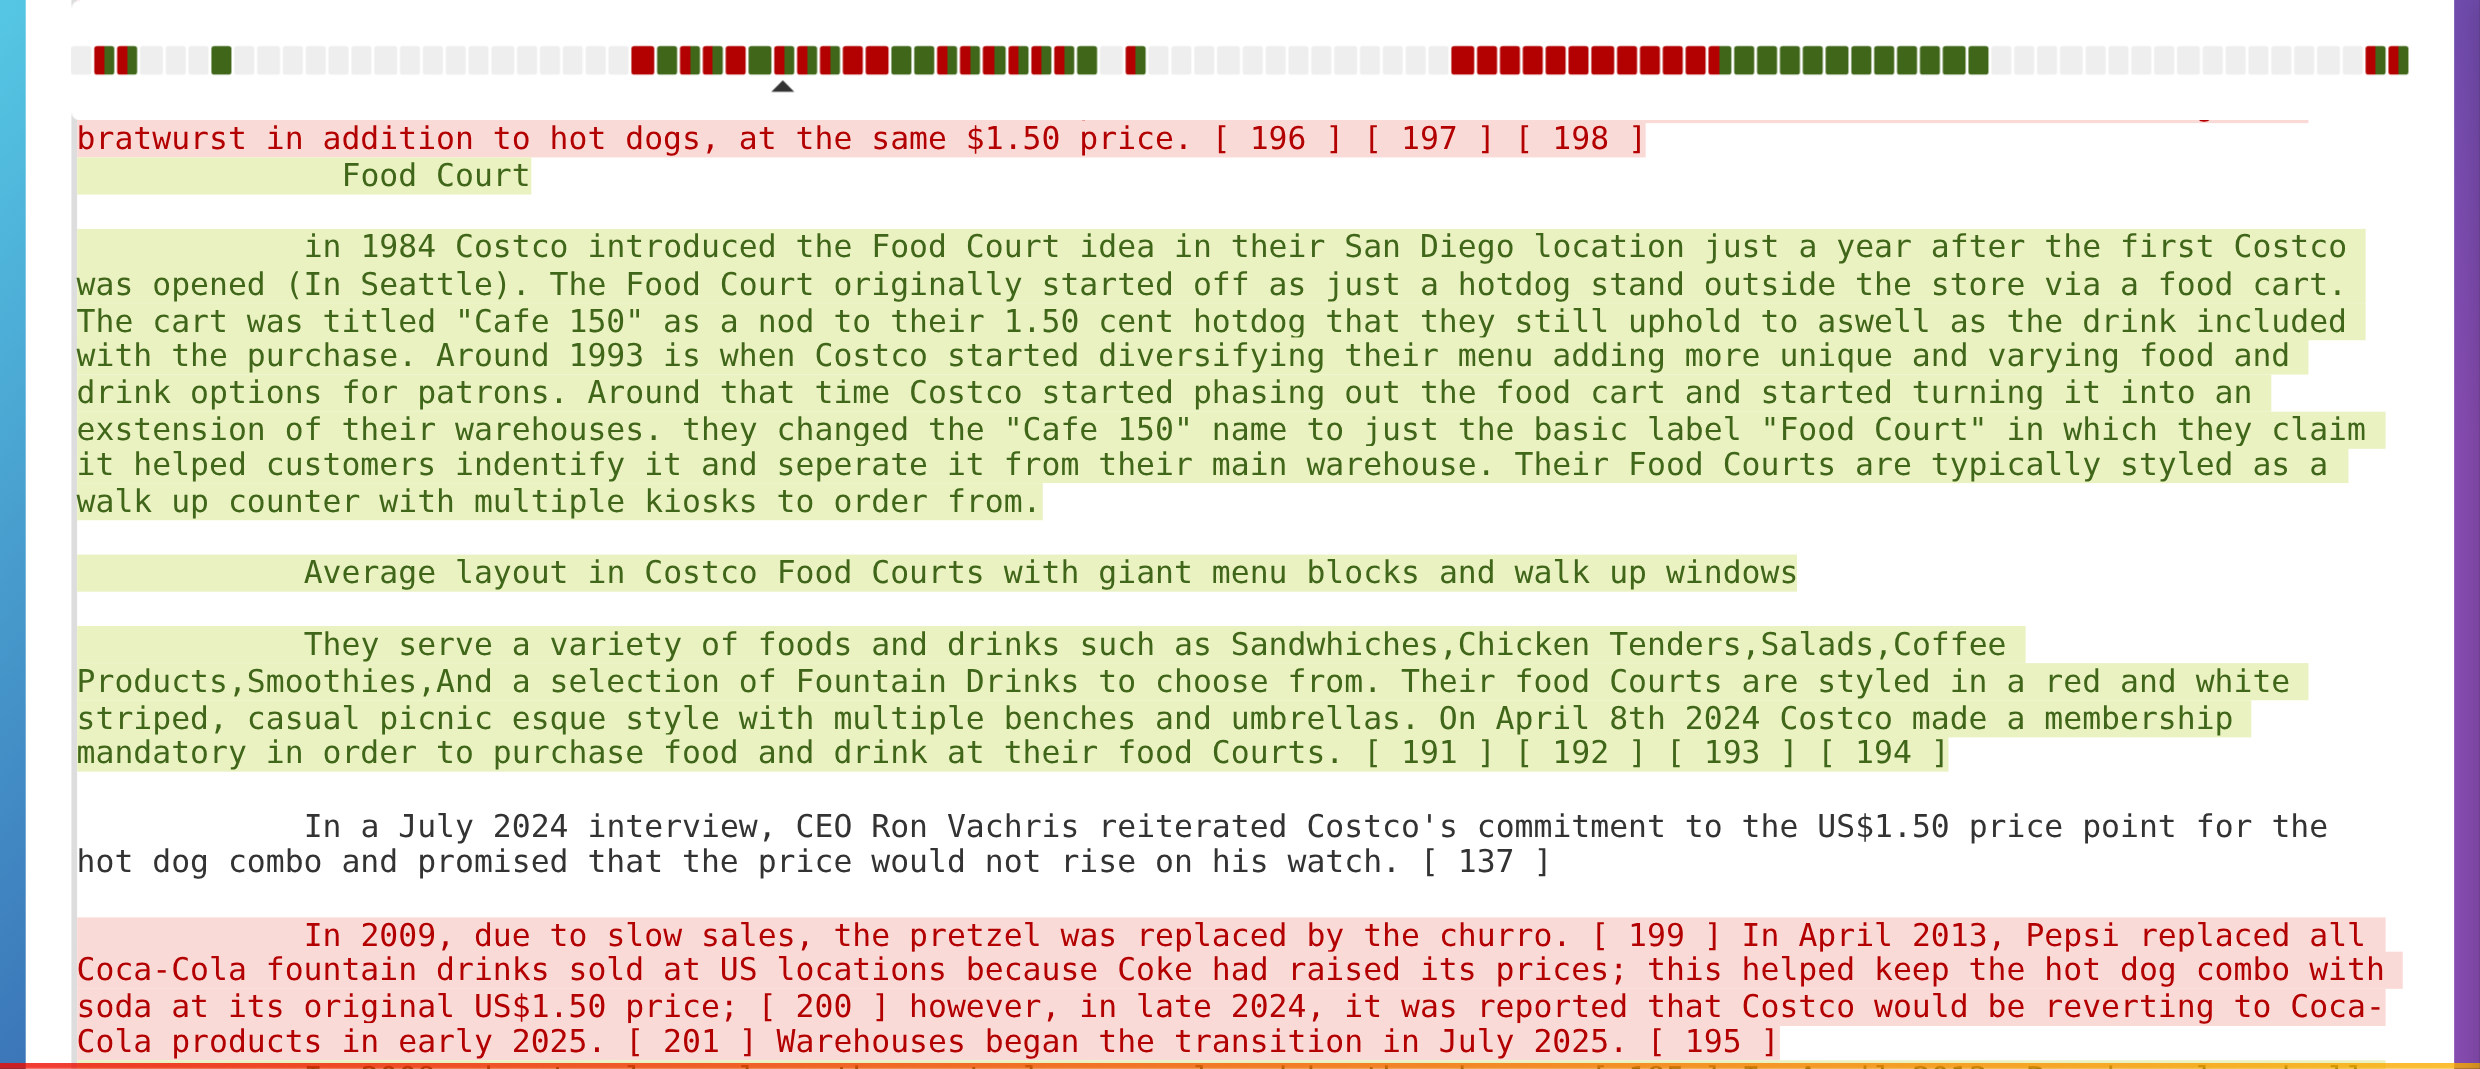
I used two real edits of the Costco Wikipedia page. Sending the whole new page would have been 35,425 tokens. changedetection.io kept only what changed between the two edits. That change list was 20,070 tokens.
my changedetection.io run · the change list · red was removed, green was added
30 / CHANGEDETECTION.IO · THE RESULT
010203040506070809
43.3% fewer tokens. Only the change.
BEFORE · THE WHOLE NEW PAGE35,425tokens · 189,928 characters
AFTER · ONLY THE CHANGES20,070tokens · 79,436 characters
43.3%FEWER TOKENS ABOUT 1.8x LESS
WHAT THIS MEANSI sent only what changed, not the whole page again.
IN THIS TEST. TIKTOKEN CL100K_BASE ESTIMATE, NOT THE GROK BOT METER. SOURCE: Costco on Wikipedia, 2 real edits
31 / REPO 7 OF 9
07
REPO 7 OF 9 · RTK
Shrink long output before you send it.
This tool shortens long command output so you send less text.
github.com/rtk-ai/rtk
56.6%FEWER TOKENS IN THIS TEST
32 / RTK · THE STEPS
010203040506070809
How to use RTK.
1STEP 1Run your command through RTK.
2STEP 2It keeps the key lines and drops extra noise.
3STEP 3Send the short output to Grok Bot.
WHAT I TYPEDrtk git log -n 30
33 / RTK · THE EXAMPLE
010203040506070809
MY TEST · RTK
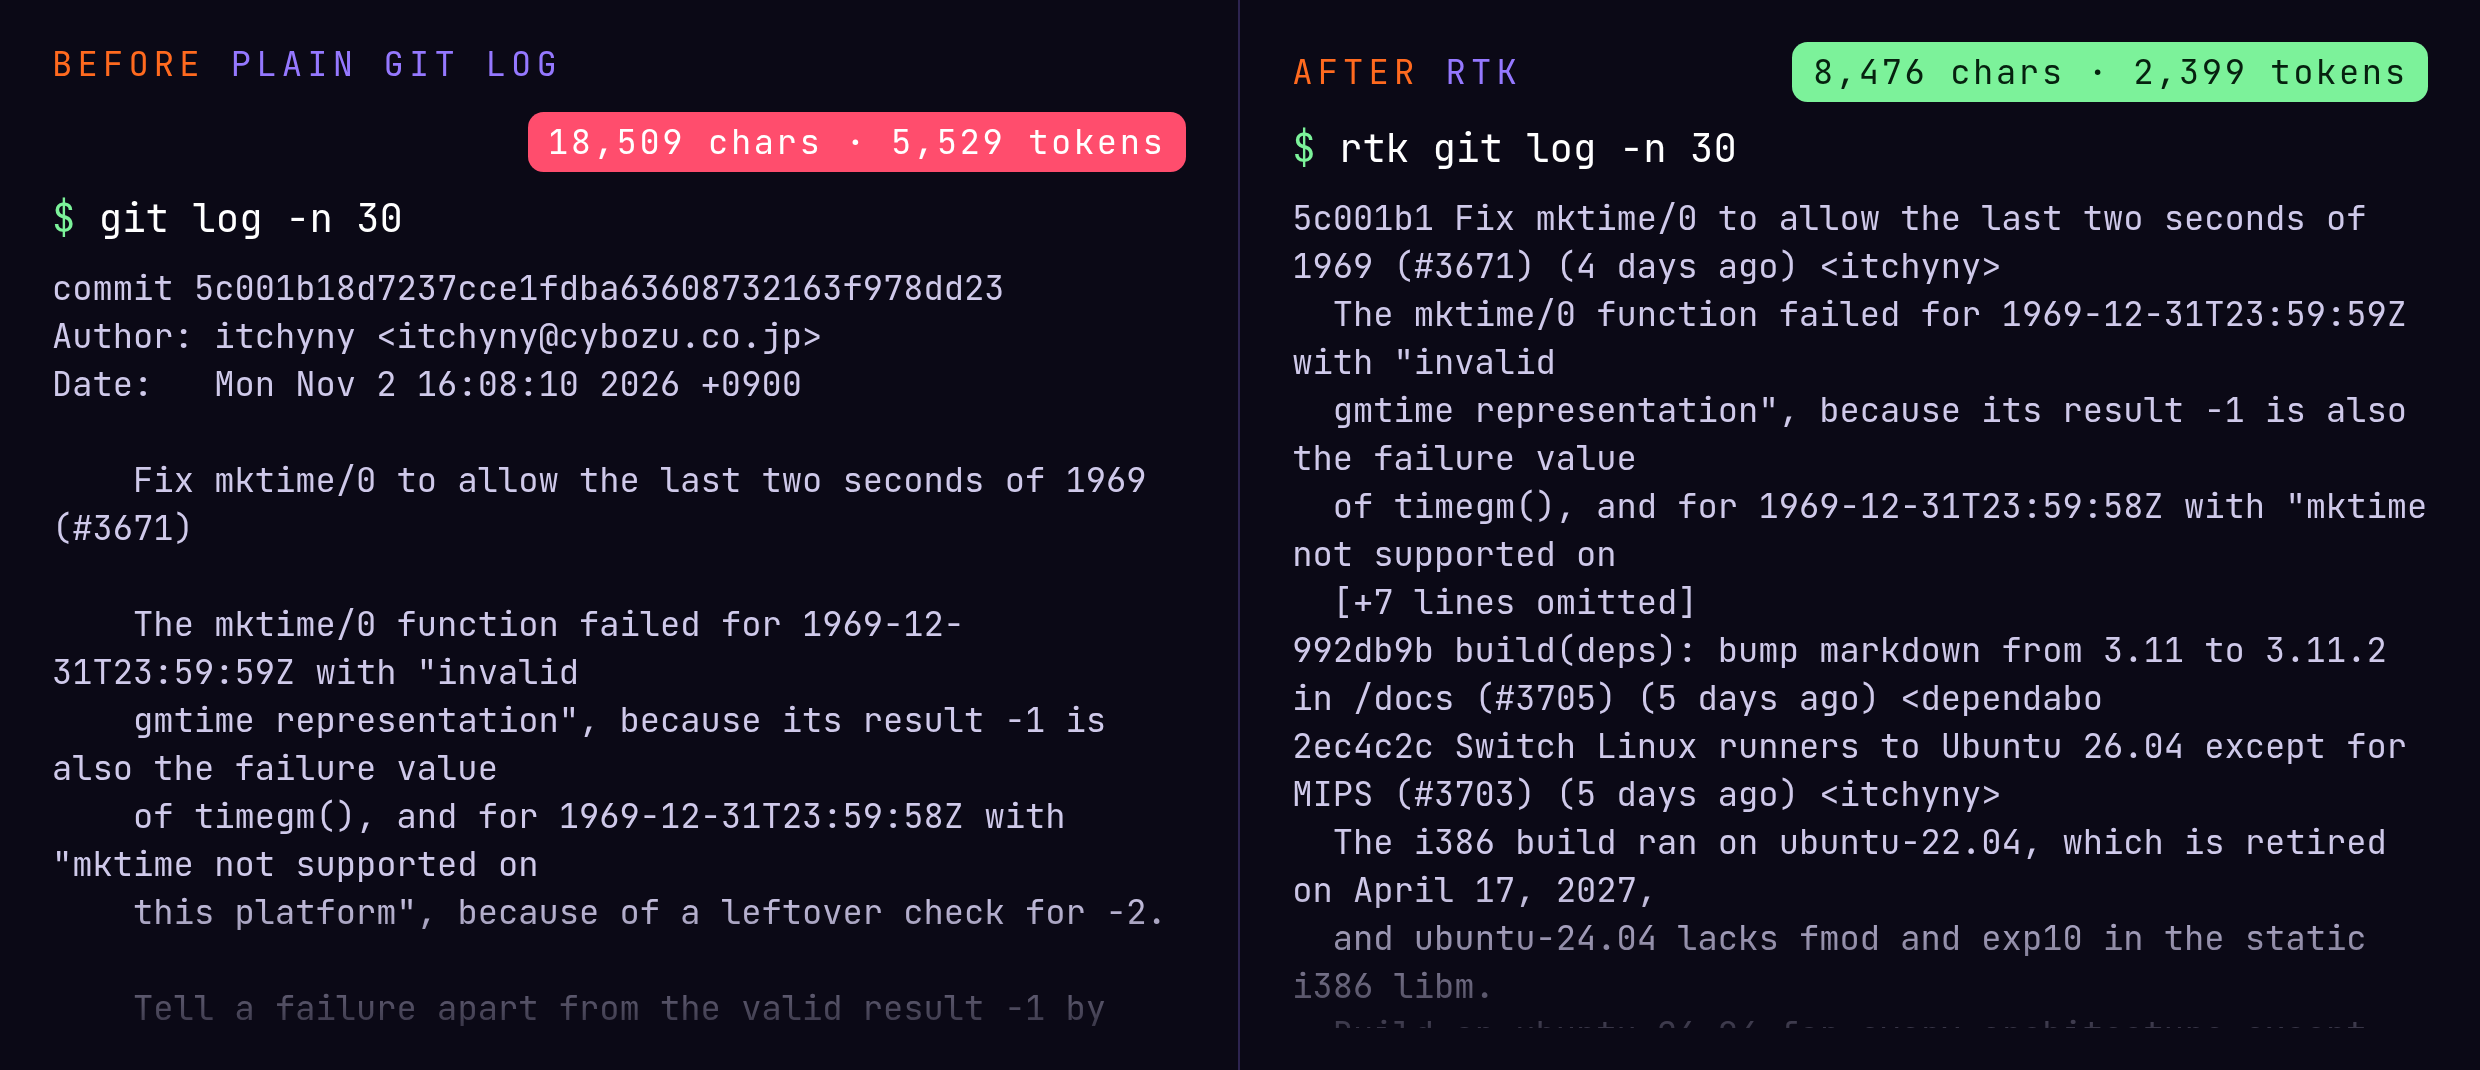
I looked at the last 30 commits from the jq project. The full git log was 5,529 tokens. I ran the same command through RTK. It shortened the log and kept the key lines, 2,399 tokens.
my files · left: the full git log · right: the same log through RTK
34 / RTK · THE RESULT
010203040506070809
56.6% fewer tokens. Same 30 commits.
BEFORE · FULL GIT LOG5,529tokens · 18,509 characters
AFTER · THROUGH RTK2,399tokens · 8,476 characters
56.6%FEWER TOKENS ABOUT 2.3x LESS
WHAT THIS MEANSSame 30 commits, a lot less text.
IN THIS TEST. TIKTOKEN CL100K_BASE ESTIMATE, NOT THE GROK BOT METER. SOURCE: jqlang/jq, last 30 commits
35 / REPO 8 OF 9
08
REPO 8 OF 9 · TENACITY
Retry one call, not the whole chat.
This tool retries one failed call in code, so you do not have to ask the bot to start over.
github.com/jd/tenacity
RETRIES IN CODENO TOKEN PERCENT
36 / TENACITY · THE STEPS
010203040506070809
How to use Tenacity.
1STEP 1Wrap the shaky call with Tenacity.
2STEP 2If it fails, it waits and tries that same call again.
3STEP 3The bot is not asked to redo the whole job.
WHAT I TYPED@retry(stop=stop_after_attempt(5), wait=wait_fixed(1))
37 / TENACITY · THE EXAMPLE
010203040506070809
MY TEST · TENACITY
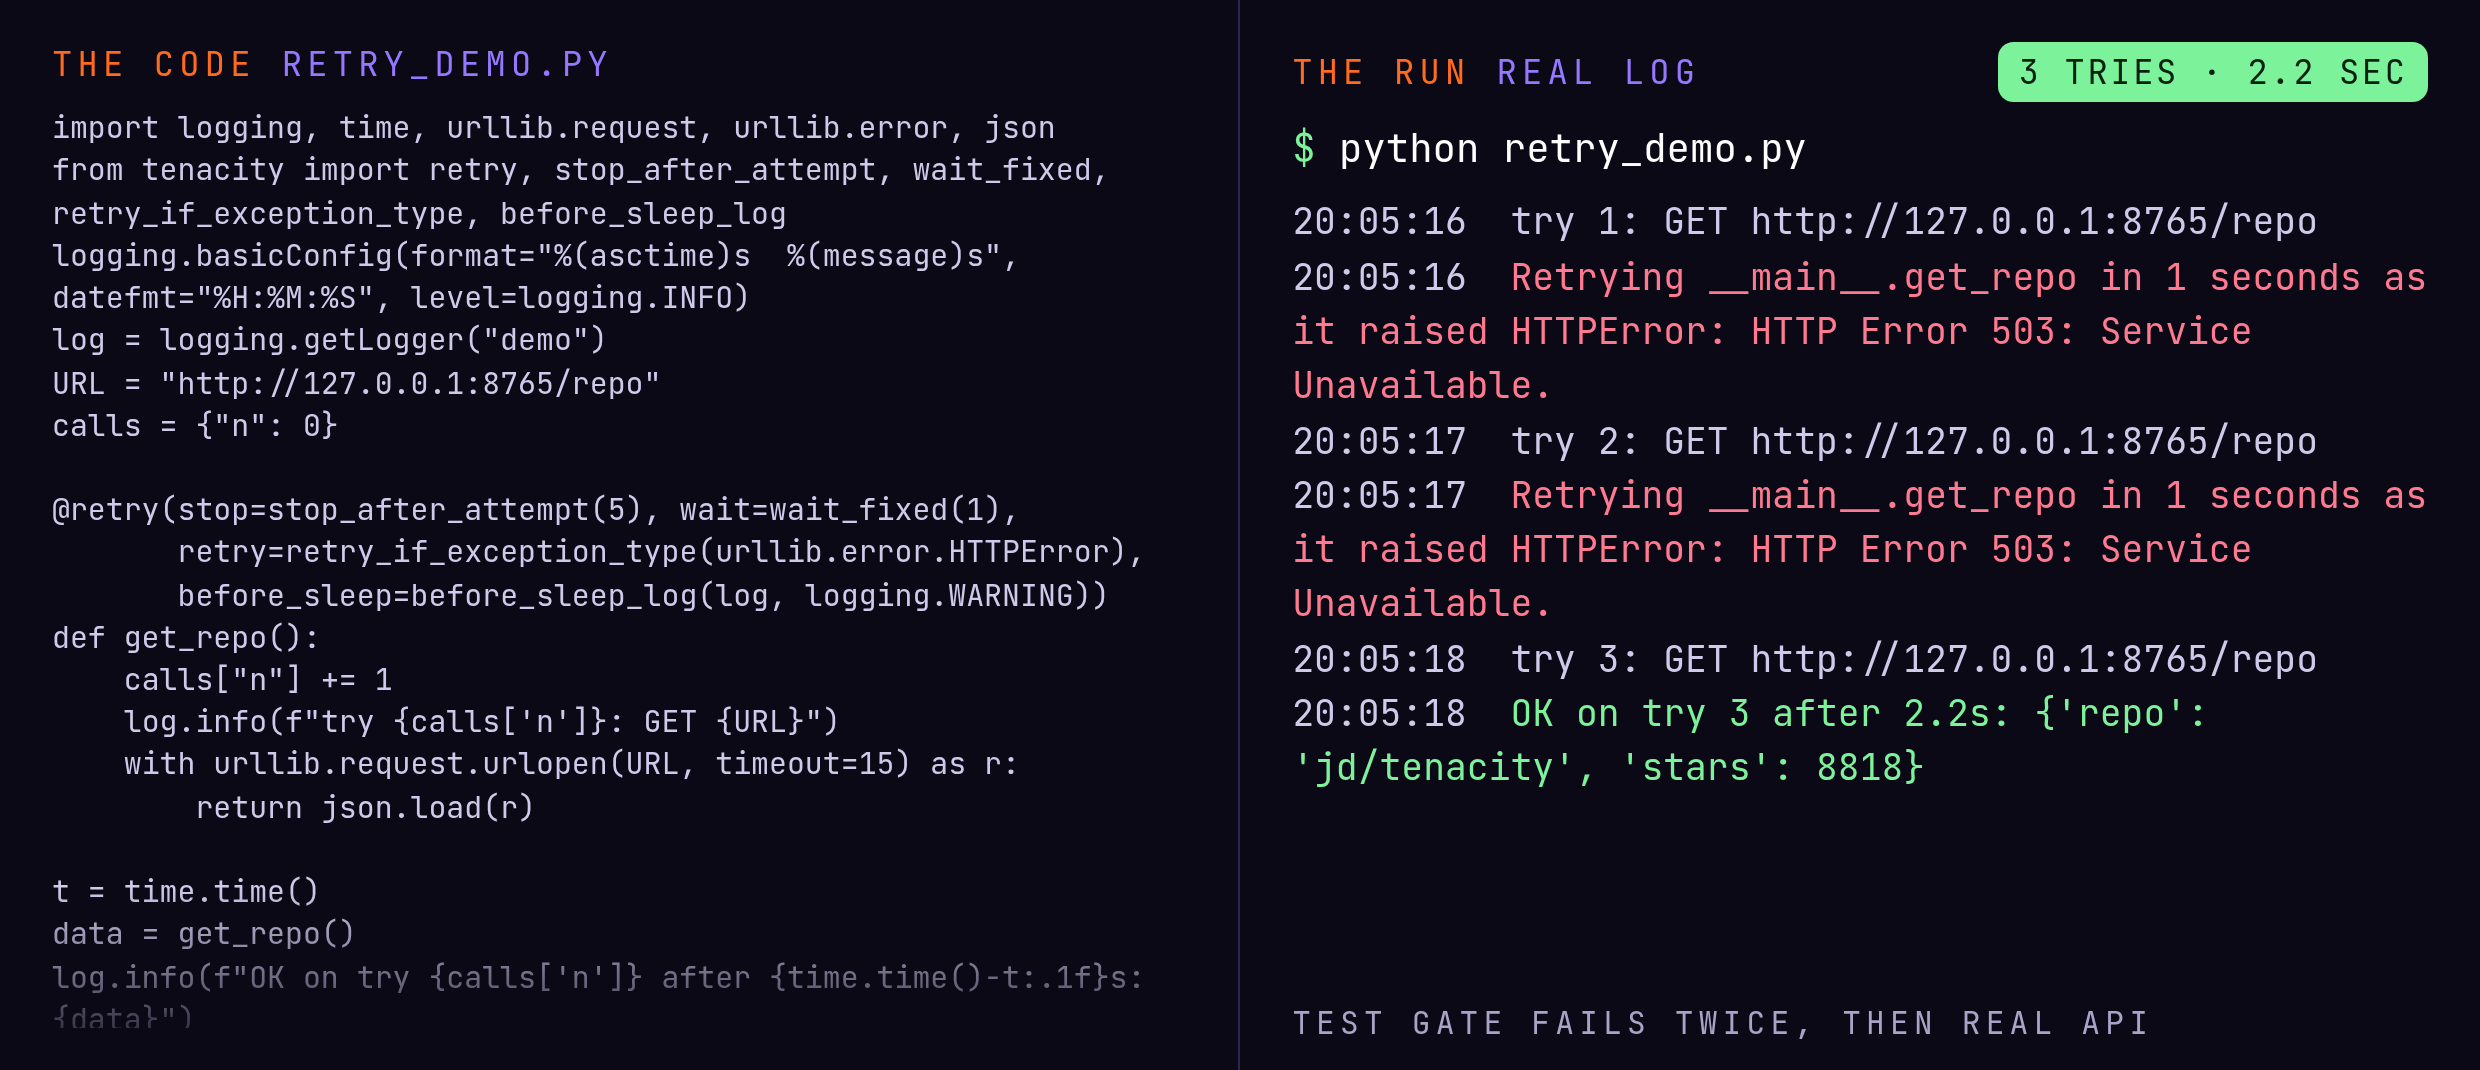
I made a call that failed on purpose twice, then worked. Tenacity retried just that one call. It tried 3 times in 2.2 seconds and got the answer on try 3. There is no token percent, because this does not shrink text.
my run · fail, fail, then OK on try 3
38 / TENACITY · THE RESULT
010203040506070809
Fixed in code. Bot not asked again.
TRY 1 AND TRY 2FAIL, FAILthe test call failed on purpose
TRY 3OK3 tries in 2.2 seconds
NO TOKEN PERCENTTHIS DOES NOT SHRINK TEXT
WHAT THIS MEANSOne call tried again. The bot was not asked to restart the job.
IN THIS TEST. NO TOKEN NUMBER CLAIMED. SOURCE: my own test call that fails on purpose
39 / REPO 9 OF 9
09
REPO 9 OF 9 · PYDANTIC
Check the shape before the next try.
This tool checks that an answer has the right shape before you use it.
github.com/pydantic/pydantic
CHECKS THE SHAPENO TOKEN PERCENT
40 / PYDANTIC · THE STEPS
010203040506070809
How to use Pydantic.
1STEP 1Say what the answer should look like.
2STEP 2Pydantic checks it on your computer.
3STEP 3If something is wrong, you fix only those bits, not the whole job.
WHAT I TYPEDRepo.model_validate_json(reply)
41 / PYDANTIC · THE EXAMPLE
010203040506070809
MY TEST · PYDANTIC
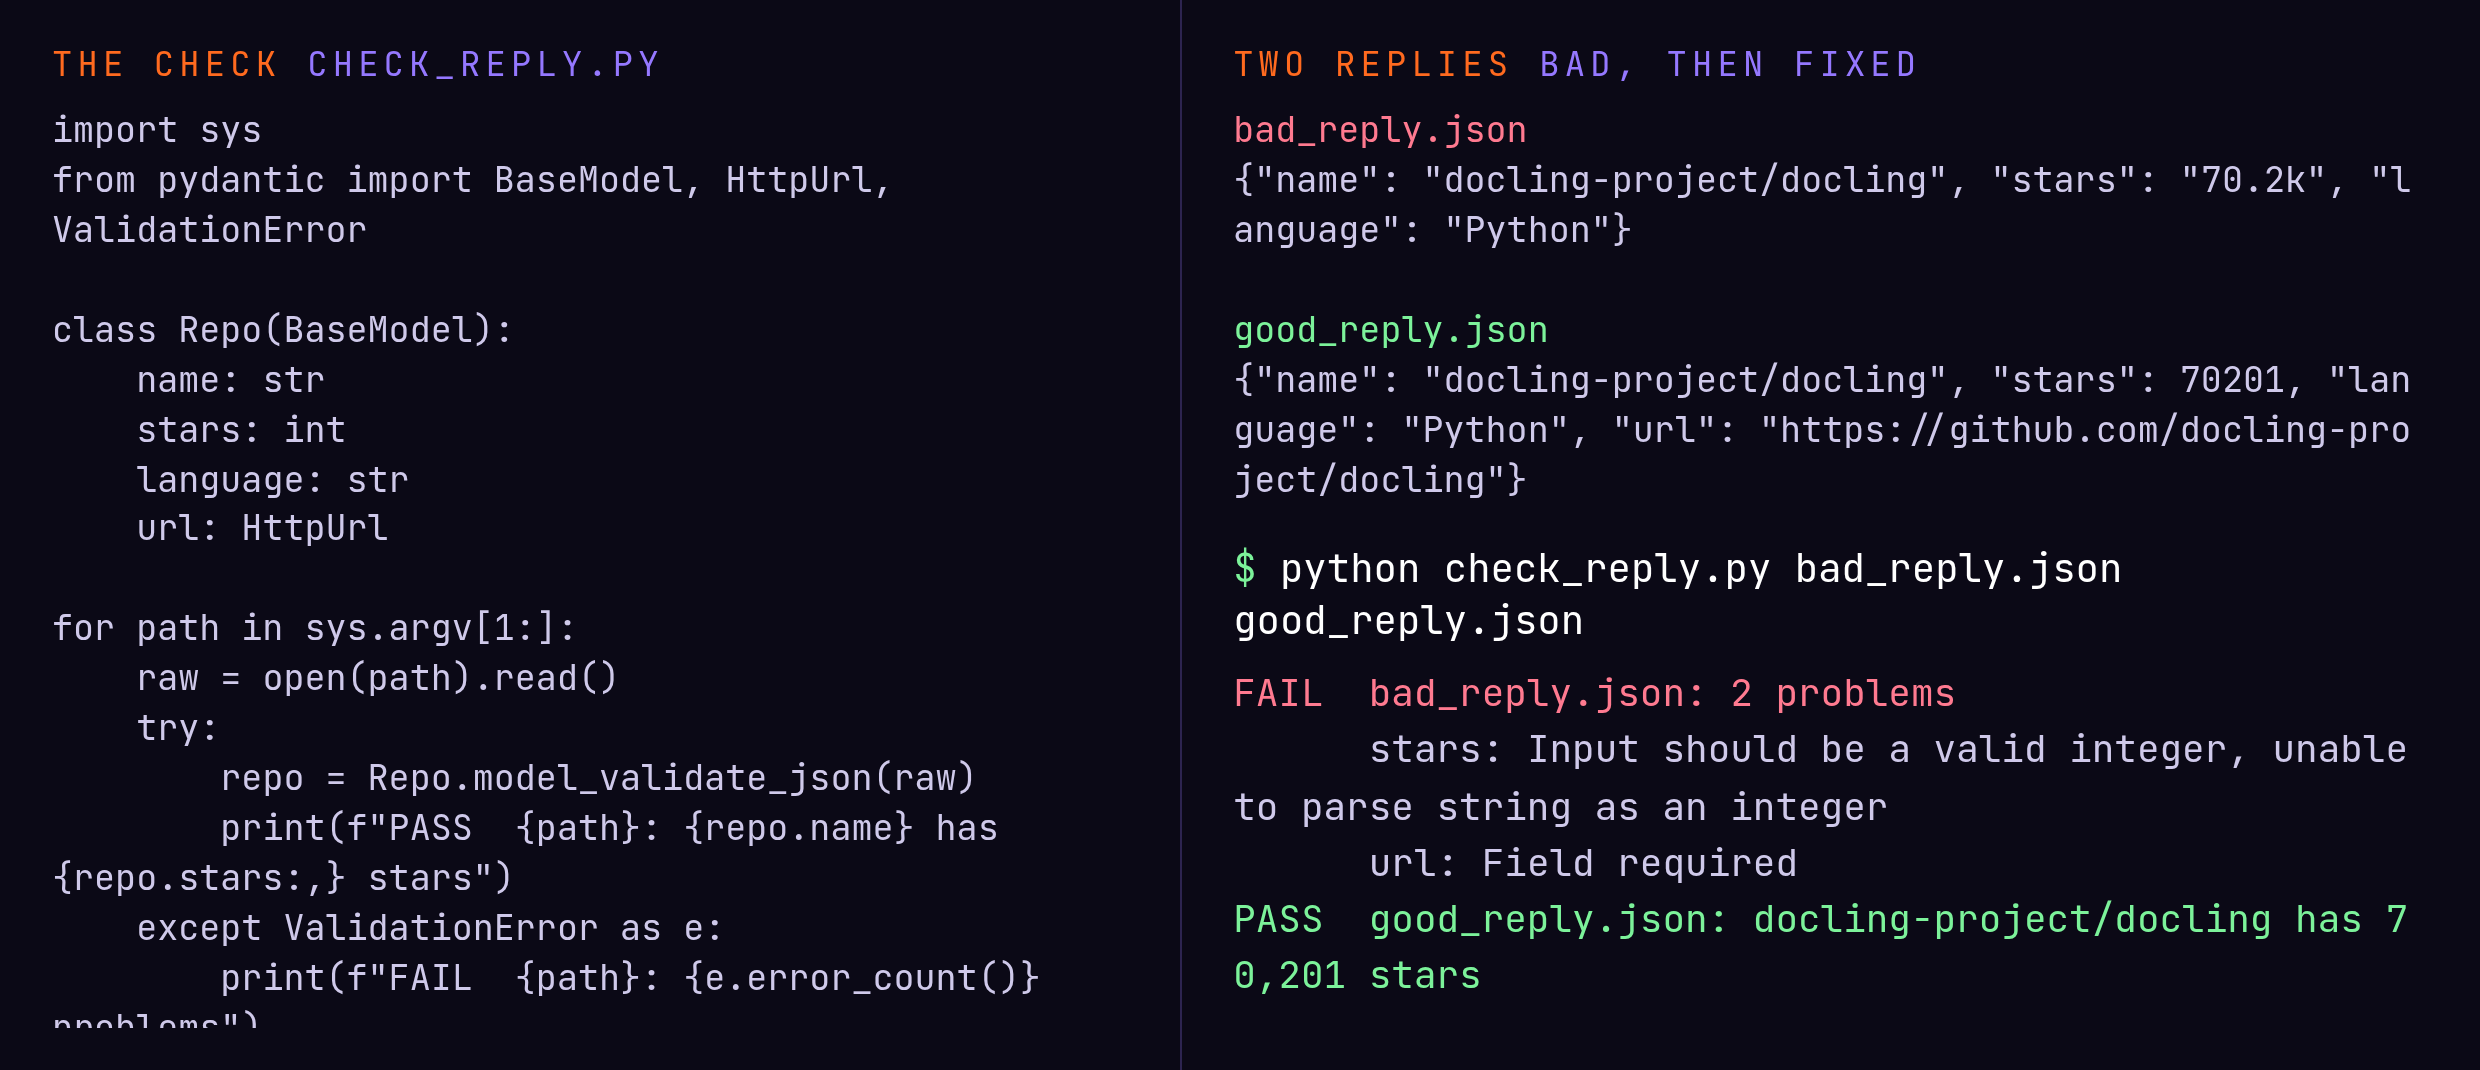
I used a sample bad reply where the star count was written as text, 70.2k, and the web address was missing. Pydantic caught 2 problems. A fixed reply passed. There is no token percent, because this does not shrink text.
my run · the bad reply fails with 2 problems, the fixed reply passes
42 / PYDANTIC · THE RESULT
010203040506070809
Caught on my computer. Before I used it.
THE BAD REPLY2 PROBLEMSstars was text "70.2k", url missing
THE FIXED REPLYPASSdocling-project/docling
NO TOKEN PERCENTTHIS DOES NOT SHRINK TEXT
WHAT THIS MEANSI fix only the 2 bad bits, not the whole job.
IN THIS TEST. NO TOKEN NUMBER CLAIMED. SOURCE: a sample bad reply + a fixed one
43 / THE RECAP
Nine tools, one habit.
01 · TRAFILATURAStrip the page, keep the words
93.3% LESS
02 · JQPick the fields you asked for
99.0% LESS
03 · RIPGREPFind the lines, skip the rest
98.8% LESS
04 · DUCKDBAsk the spreadsheet, don't paste it
99.99% LESS
05 · DOCLINGTurn a PDF into cleaner text
38.2% LESS
06 · CHANGEDETECTION.IOSend only what changed
43.3% LESS
07 · RTKShrink long output before you send it
56.6% LESS
08 · TENACITYRetry one call, not the whole chat
RETRY IN CODE
09 · PYDANTICCheck the shape before the next try
CHECK LOCALLY
PERCENTS ARE FEWER TOKENS SENT IN THIS TEST ONLY. TIKTOKEN CL100K_BASE ESTIMATE.
44 / THE PROMPT
PASTE THIS INTO GROK BOT · SAVE IT AS A SKILL
Save this as a skill called "Lean Input". Use it before you read anything big.THE GOAL
Do the same job, but send less text into this chat. Never read a raw dump when a free tool can cut it down first.SET UP (once)
pip install trafilatura duckdb docling changedetection.io tenacity pydantic
Install jq, ripgrep and RTK from their official releases.
If a tool is missing, install it first, then carry on.THE 9 RULES
1. A web page link: get clean text with trafilatura, not the raw HTML.
trafilatura-u"URL"--output-formattxt2. JSON or an API reply: pull only the fields the job needs with jq.
curl-s"URL"|jq'{name,price}'3. A folder of files: search first with ripgrep, then read only the lines that match.
rg-n"word"folder/4. A CSV or spreadsheet: load it in DuckDB and ask one SQL question. Read only the result.
SELECTcol,count(*)FROM'file.csv'GROUPBYcol5. A PDF or Word file: turn it into markdown with Docling first.
doclingconvertfile.pdf--tomd6. A page I want watched: track it with changedetection.io. Read only the change, never the whole page again.7. Long command output (git, tests, logs): run it through RTK so the output is short.
rtkgitlog-n308. A flaky API: retry the call in code with Tenacity. Do not redo the whole job in chat.9. A structured answer: check it with a Pydantic model in code. If it fails, fix only the fields that failed.HOW TO REPORT
- Each time you cut something, tell me the size before and after, in characters.
- If a tool might drop something the job needs, say so and use the full text for that part.
- Never make up numbers.
 GROK BOT TOKEN USAGE